What is named entity recognition (NER) annotation used for in LLM training?
TL;DR
- Named entity recognition (NER) annotation labels specific spans of text, such as people, organizations, locations, dates, or domain-specific entities, so a model can learn to identify and classify them.
- In LLM training, NER-labeled data supports structured information extraction, grounding factual answers, and building or evaluating downstream tasks like search, compliance screening, and document processing.
- NER also underlies more specialized domain taxonomies, such as tagging personally identifiable information categories or coding medical terminology.
- Good NER annotation depends on consistent entity definitions and strong inter-annotator agreement, since ambiguous entity boundaries are one of the more common sources of label noise in text datasets.
Any large language model that can pull a name, a date, or a company out of a block of text owes that ability, at least in part, to named entity recognition annotation. NER is one of the oldest annotation types in natural language processing, and it predates the current wave of generative models by decades. The task sounds simple when you first describe it. You read a sentence, and you mark which words refer to a person, which refer to a place, which refer to an organization, and so on. But that simplicity hides a lot of careful decision-making, and the quality of those decisions shapes how well a model learns to find and reason about the specific, identifiable things in a piece of text.
This article walks through what NER annotation actually involves, how NER-labeled data feeds into training and evaluating LLMs, and why the task gets much harder once you move past generic people-and-places tagging into domain-specific taxonomies like personally identifiable information categories or medical terminology coding. It also looks at what separates a well-built NER program from a noisy one, and what that difference should mean when you are picking a data annotation partner. If you are new to the broader category, the data annotation glossary entry covers the surrounding terms, and this piece zooms in on one of them.
What named entity recognition annotation is
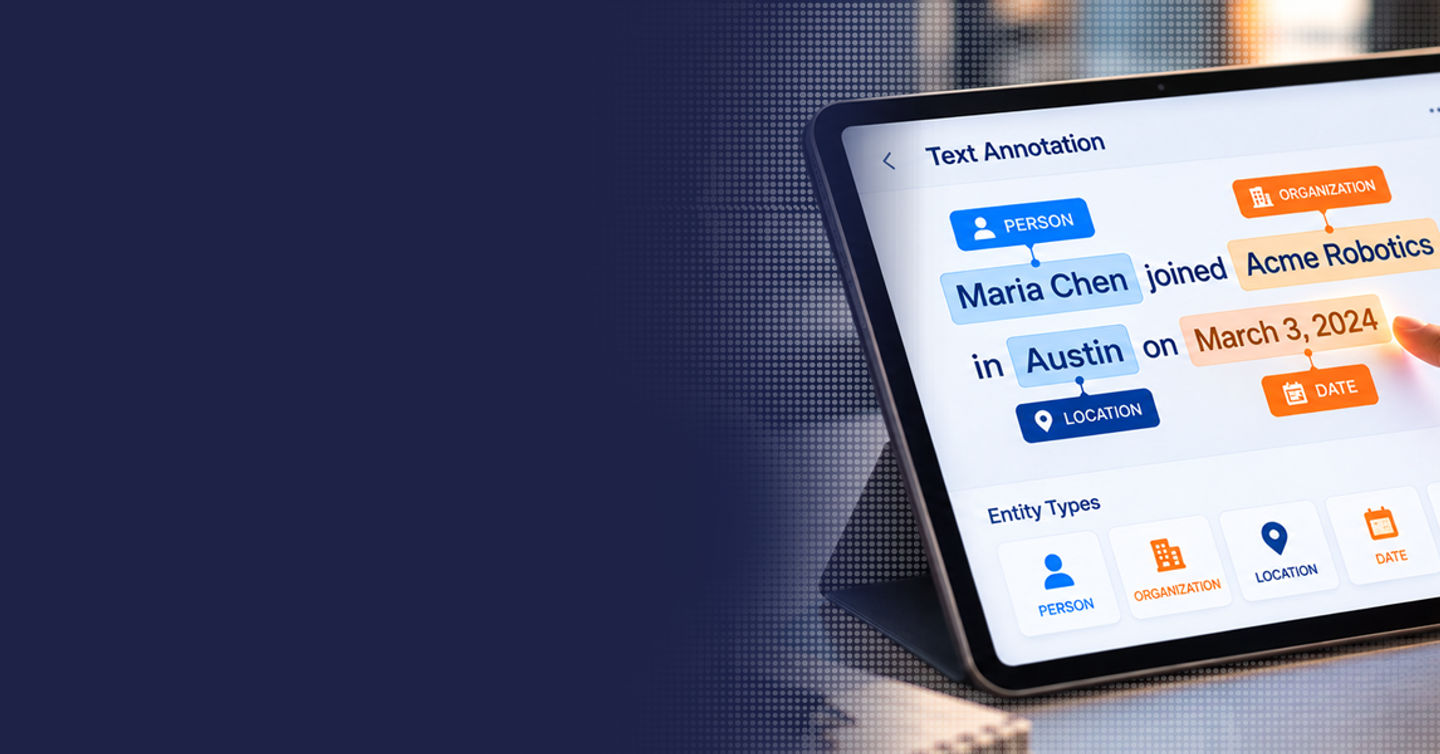
At its core, NER annotation is the work of marking spans of text and assigning each one an entity type. Take a sentence like "Maria Chen joined Acme Robotics in Austin on March 3, 2024." A person doing NER annotation would label "Maria Chen" as a person, "Acme Robotics" as an organization, "Austin" as a location, and "March 3, 2024" as a date. The output is not a summary or a rewrite. It is the original text with a set of labeled spans attached, each span pointing at the characters it covers and the category it belongs to.
That is different from simple keyword matching, and the difference is the whole point. A keyword list can catch "Acme Robotics" if someone put "Acme Robotics" on the list. It cannot catch "Acme Robotics Incorporated," or "ACME Robotics," or a brand-new company the list has never seen. NER annotation, used as training data, teaches a model the pattern of what an organization looks like in context, so the model can generalize to phrasings and names it has never encountered. The model learns that a capitalized multi-word phrase following "joined" and preceding a location is probably an organization, even when the exact string is new. That ability to generalize to unseen phrasing is what makes NER useful rather than brittle.
The genuinely hard part of NER is usually not deciding whether something is a person or a place. It is deciding where an entity starts and stops, and what to do when entities nest inside each other. Consider "University of Texas at Austin School of Law." Is that one entity, the full name of a specific law school? Or is it an organization ("University of Texas at Austin") containing another organization ("School of Law")? And is "Austin" inside it a separate location, or is it just part of the university's name? There is no single correct answer that holds for every project. A legal research dataset might want the whole string as one organization. A geographic dataset might want "Austin" pulled out as a location regardless of what surrounds it.
What matters more than which boundary choice you make is that you make the same choice every time. A scheme that consistently treats "University of Texas at Austin School of Law" as a single nested organization will produce cleaner training data than a scheme that sometimes splits it, sometimes nests it, and sometimes grabs only the first few words. The same logic applies to "Acme Robotics" versus "Acme Robotics Incorporated." Pick a rule for whether the legal suffix is part of the entity, write it down, and apply it uniformly. Inconsistency, not the specific rule, is what poisons a dataset. This is why serious NER work leans so heavily on written annotation guidelines and boundary conventions rather than leaving each annotator to use their own judgment.
How NER annotation is used in LLM training
NER-labeled data shows up in LLM development in three broad ways, and they build on each other.
The first is structured information extraction. A large share of the world's useful information sits in unstructured text: contracts, support tickets, clinical notes, regulatory filings, news articles. NER annotation teaches a model to pull the structured facts out of that prose, turning "Maria Chen joined Acme Robotics in Austin on March 3, 2024" into fields a database can hold. Once a model is reliable at recognizing entities, you can chain that into tasks like populating a CRM from email, summarizing a filing by its parties and dates, or flagging every account number mentioned in a document. The extraction is only as good as the entity recognition underneath it, which is why the annotation quality at the bottom of that stack matters so much.
The second is grounding. Before a model can search for an entity, verify a claim about it, or reason over it, the model has to correctly identify which real-world thing a name refers to. "Washington" might be a person, a state, a city, or an organization depending on the sentence. Getting that right is a prerequisite for retrieval. In retrieval-augmented generation (RAG) systems, which fetch documents to support an answer, mis-identifying the entity in the question sends the retrieval step looking for the wrong thing, and the model then grounds its answer in irrelevant material. NER-style entity disambiguation is one of the quiet, load-bearing steps that decides whether a RAG pipeline returns the right document or a confidently wrong one.
The third is evaluation. NER-labeled test sets are a practical way to measure whether a model actually recognizes the entities it is supposed to, broken down by type and by domain. Aggregate accuracy on a general benchmark can look healthy while the model quietly fails on a narrow but important category, such as recognizing drug names or legal case citations. A targeted NER evaluation set exposes those domain gaps and catches narrow regressions that a single headline number would mask. If a model update improves overall scores but silently gets worse at tagging dates in financial documents, a well-constructed NER test set is where you find out before your users do.
NER beyond generic entities: domain-specific taxonomies
Generic NER, people, organizations, locations, dates, is a well-understood problem, and the gap between vendors on that basic task is not large. The work gets much more demanding when the entity types stop being generic and start encoding domain knowledge. Two examples make the difference concrete.
The first is PII tagging for financial services. A compliance or audit workflow does not want a vague "number" label. It wants to distinguish an account number from a Social Security number from a date of birth from a routing number from a residential address, because each of those carries different handling obligations and different regulatory exposure. Labeling a Social Security number as a generic "identifier," or missing it entirely, is not a cosmetic error. In a financial compliance setting it can mean sensitive personal data flows into a place it was never supposed to go, with real regulatory consequences attached. The entity types here are fine-grained on purpose, and the annotator has to understand what each category means and why the line between them matters. The banking and financial services GenAI Data Services work is built around exactly this kind of regulated, fine-grained labeling.
The second is MedDRA coding in healthcare. MedDRA, the Medical Dictionary for Regulatory Activities, is a standardized terminology used to code medical events, and mapping a plain-language description to the right code is not a lookup. The same phrase a patient uses can map to different codes depending on clinical context. "Feeling sick" might map to nausea, to general malaise, or to something more specific, and the right choice depends on the surrounding record and real clinical judgment. An annotator without medical training will guess, and the guesses will be inconsistent in ways that are hard to catch downstream. This is annotation that needs a person who understands the domain, applied under HIPAA-compliant healthcare workflows, because the data being labeled is protected health information.
In both cases the mechanical act is the same as generic NER: mark a span, assign it a type. The taxonomy is the part that changes, and the knowledge required to apply the taxonomy correctly is the part that is genuinely hard to staff. That distinction, same mechanic, very different expertise, is the thread that runs through the rest of this article.
What makes NER annotation quality high or low
Three things separate NER annotation you can train on from NER annotation that quietly degrades a model.
The first is clear entity definitions and boundary rules that every annotator shares. This is the written answer to the "University of Texas at Austin School of Law" problem from earlier. A good NER project has a document that says, in plain terms, what counts as each entity type, where boundaries fall, how to handle nested entities, and what to do with the edge cases that keep coming up. Without it, every annotator improvises, and improvisation does not agree with itself across a team.
The second is a consistent tagging scheme with proper versioning when the taxonomy changes mid-project. Real projects evolve. Someone realizes halfway through that "product" and "product line" need to be separate types, or that a new PII category has to be added. When that happens, the change has to be versioned and the already-labeled data has to be reconciled against the new scheme, or the dataset ends up with two incompatible labeling conventions sitting side by side. Taxonomy drift without versioning is one of the easier ways to introduce silent inconsistency into a dataset that otherwise looks fine.
The third is inter-annotator agreement, which is the metric that tells you whether the first two are actually working. You give the same text to more than one annotator and measure how often they produce the same labels. High agreement means your definitions are clear enough that different people reach the same answer. Low agreement is an early warning that the entity definitions are ambiguous and need to be fixed before more data gets labeled. It is cheaper to catch a confusing boundary rule when two annotators disagree on a hundred sentences than to discover it after a million are labeled.
The stakes here are easy to underrate because each individual disagreement looks trivial. Research on label quality in widely used machine learning benchmark datasets, published by MIT CSAIL (Curtis Northcutt and colleagues), found an average label error rate of about 3.3 percent across commonly used datasets. That sounds small until you consider how those errors compound. Separate research on noisy labels, cited via SitePoint, has documented accuracy drops of roughly 25 percent when noisy labels enter training data. A single mis-drawn entity boundary is tiny. A consistent pattern of mis-drawn boundaries, repeated across a dataset because the guidelines were unclear, is the kind of thing that pulls real accuracy out of a model.
A small, everyday example shows how this plays out. Imagine a customer support dataset where annotators are tagging entities in chat transcripts, and one of the entity types is the customer's account. In one transcript an annotator tags "the account" as the account entity. In another, a different annotator decides "the account" is too generic and only tags it when an actual account number appears. Neither choice is obviously wrong, but the two of them together mean a model trained on the data sees the same phrase labeled two different ways. Multiply that across a team and a few months, and the inconsistency is no longer an edge case. It is a measurable source of noise, and it traces straight back to a definition that was never pinned down.
Why this matters when choosing a data annotation vendor
Here is the practical takeaway for anyone evaluating annotation partners. Generic NER is a commodity. Most competent vendors can label people, organizations, locations, and dates reasonably well, and the gap between them on that task is small enough that it is a poor basis for a decision. The real differences show up in domain-specific taxonomy work, where the annotator has to understand financial compliance categories or clinical terminology well enough to apply them consistently under pressure.
So when you are assessing a prospective vendor, do not ask them to demonstrate generic NER. Ask them to walk you through building a taxonomy from scratch for a domain like yours, not just applying an existing one. Building a taxonomy means deciding what the entity types should be, writing the definitions and boundary rules, versioning the scheme as it changes, and setting up the inter-annotator agreement checks that keep it honest. That is the work that is hard to fake, and it is the work that actually determines whether your labeled data is clean. Ask for concrete examples in a comparable industry, and listen for whether they talk about domain expertise and consistency or just throughput and tooling.
A vendor that leads with how fast it can tag generic entities is answering a question that was not the hard one. A vendor that can describe how it built a fine-grained PII scheme for a bank, versioned it when the regulations shifted, and held inter-annotator agreement steady while doing it, is describing the capability that actually separates good training data from noisy training data.
See how Firstsource applies structured entity labeling to regulated industries
If you are weighing how NER-style annotation should work for your own training data, the clearest way to judge a partner is by what they have built in regulated, domain-heavy settings. Explore data annotation solutions to see how structured entity labeling is applied where the taxonomy, and the domain knowledge behind it, is the hard part.
FAQ
What is named entity recognition (NER) annotation used for in LLM training?
NER annotation labels spans of text as specific entity types, such as people, organizations, locations, and dates, which helps train and evaluate a model's ability to extract structured information and ground factual answers in text. It gives an LLM the foundational skill of recognizing which parts of a sentence refer to a specific, identifiable thing, before the model can reliably search for it, verify it, or reason about it.
What are examples of entities labeled in NER annotation?
Common examples include person names, organization names, locations, dates, and product names. Many applications also use custom, domain-specific entity types, such as PII categories in financial services or medical terminology in healthcare, built on top of the same core tagging logic.
How is NER annotation different from text classification?
Text classification labels an entire document or passage with a single category, such as marking an email as spam or not spam. NER annotation works at a finer level, labeling specific spans of text within that same document as individual entities, such as the sender's name or company.
Why is inter-annotator agreement important for NER annotation?
Entity boundaries are often ambiguous, so measuring how consistently different annotators label the same entities reveals whether a tagging scheme is clear enough to produce reliable training data. A low agreement score is usually a sign that the entity definitions need to be clarified before more data gets labeled.
Can NER annotation be customized for a specific industry?
Yes. Many organizations build custom entity taxonomies for their domain, such as personally identifiable information categories in financial services or medical terminology coding in healthcare, instead of relying on generic entity types alone. The underlying annotation process stays the same; only the taxonomy and the domain knowledge required to apply it change.