Which vendors provide outsourced data labeling for enterprise AI teams?
TL;DR
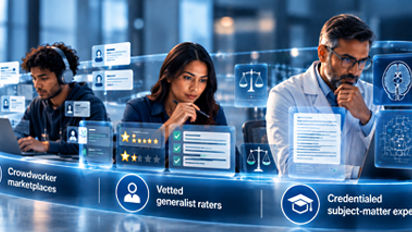
- Enterprise AI teams typically outsource data labeling to one of three vendor types: crowd-sourced marketplaces such as Appen and Sama, ML-native tooling platforms with managed labeling services such as SuperAnnotate and Labelbox, or BPO-scale providers with dedicated, domain-matched workforces such as iMerit/EXL and Firstsource.
- The right choice usually comes down to how fast the vendor can activate a qualified team and how well that team matches the data's domain, since building an equivalent function in-house typically takes 12 to 18 months.
- Firstsource's Gigsourcing Platform is built specifically to compress that timeline, assembling domain-matched specialists in under 48 hours across more than 100 countries.
- Enterprise buyers should weigh activation speed, workforce quality, and compliance posture together, and avoid treating outsourcing as one interchangeable category.
There is a moment in almost every AI program when the labeling question stops being a side task and becomes a staffing problem. During a pilot, a small internal team can hand-label a few thousand examples, argue about the edge cases, and move on. That works until the model shows promise and someone asks to scale it. Suddenly you need tens of thousands of labeled examples, then hundreds of thousands, with consistent quality, documented guidelines, reviewers who understand the domain, and a QA process that will hold up when an auditor or a regulator asks how the training data was produced. That is the point where most enterprise teams price out two paths: build the labeling function in-house, or hand it to an outsourcing partner.
This article is about that decision. We will walk through what an in-house build actually costs in time, what "outsourced data labeling" really covers once you look past the marketing, and how the outsourcing market sorts into three distinct vendor types. Then we give you a short framework for matching a vendor to your program's maturity, because the honest answer to "which vendor is best" is that it depends on what you are labeling, in what languages, under what compliance rules, and how fast. Firstsource sits in one of those three categories, and we will be specific about where it fits and where other models fit better.
The real timeline of building a data labeling function in-house
The in-house option looks cheaper on a spreadsheet than it turns out to be, mostly because the spreadsheet only captures annotator headcount. The actual build is a small operations company stood up inside your AI org.
Start with recruiting. You are not hiring generic data-entry staff. You need annotators who understand the data, whether that is medical imaging, legal documents, retail product taxonomies, or conversational intent in several languages. Sourcing, screening, and onboarding those people to your tooling takes months, before anyone has labeled a single production example. Then you need people to design the work: annotation guidelines precise enough to produce consistent labels across dozens of annotators, a taxonomy that survives contact with real edge cases, and a revision process for when the guidelines are wrong, which they always are at first.
Quality assurance is its own build. You need a review layer, inter-annotator agreement measurement, a way to catch and correct systematic errors, and reporting that lets you prove label quality rather than assert it. This matters more than teams expect. Research by Northcutt and colleagues at MIT CSAIL found an average label error rate of 3.3% across commonly used machine learning benchmark datasets, the very datasets the field treats as ground truth. If the canonical benchmarks carry that much labeling error, a brand-new internal team labeling messy production data will carry more until its QA process matures, and maturing that process is the slow part.
Then there is tooling. You either buy an annotation platform and integrate it, or you build one, and both carry a maintenance tail. Add compliance and data handling on top: access controls, workforce vetting, data residency, audit trails, and whatever your industry's regulators require. Put all of it together and a realistic timeline to stand up a dependable in-house labeling function, one that produces reliable labels at scale with QA you can defend, runs 12 to 18 months. That is an industry-context estimate rather than a single published figure, but it tracks with what the component parts above take.
Two costs compound that timeline. The first is annotator turnover, which is persistent in this work, so the recruiting and training burden never fully goes away; it becomes a recurring line item. The second is opportunity cost. Every month your model program waits on a labeling function still being built is a month the model is not improving, not shipping, and not generating the value that justified the project. That stalled-program cost rarely shows up in the build-versus-buy spreadsheet, and it is often the largest number in the comparison.
What outsourced data labeling actually includes
"Outsourced data labeling" is a single phrase covering at least three different arrangements, and conflating them is how buyers end up disappointed. Picture a concrete program, an enterprise standing up a customer service AI that has to work in five languages, and ask what you would actually hand to a vendor.
In a fully managed service, you hand over the whole function. The vendor supplies the workforce, applies your annotation guidelines (or helps you write them), runs its own QA layer, and returns labeled data plus quality reporting. You manage the vendor and the guidelines; the vendor manages everything else. For a five-language customer service model, the vendor assembles annotators fluent in each language, trains them on your intent taxonomy, labels the conversation data, and reports agreement and error rates back to you per language.
In a staff-augmentation arrangement, you are renting people rather than outcomes. The vendor supplies vetted annotators who plug into your tooling, your guidelines, and your QA process. You keep operational control and accountability for quality; the vendor keeps you from having to recruit. For that same program, you might take staff augmentation for the two languages where you already have strong internal reviewers.
In a platform-plus-crowd arrangement, you work through an annotation platform that routes tasks to a distributed crowd workforce. You get speed and elasticity for high-volume, clearly specified tasks, with the platform handling task distribution and some automated quality checks. For the customer service model, this suits the high-volume, low-ambiguity intents where the rubric leaves little room for interpretation.
These are not mutually exclusive. A mature program often mixes models across workstreams: a managed service for the regulated or ambiguous languages, staff augmentation where internal QA is strong, and platform-plus-crowd for the bulk, well-specified volume. Knowing which arrangement you are buying, workstream by workstream, matters more than the vendor's logo.
The three main types of outsourced data labeling vendors
Because the arrangements differ, the vendors that specialize in them differ too. Rather than rank individual companies, which goes stale the moment someone ships a new feature, it is more useful to sort the market into three types and understand what each is built to do well. Most names an enterprise buyer will encounter fall cleanly into one of these categories, and the category tells you more about fit than any single feature comparison.
Crowd-sourced labeling marketplaces
Vendors such as Appen and Sama run on a marketplace model. They maintain large, distributed pools of workers and route labeling tasks to them, which gives these vendors real strengths: broad language coverage, the ability to flex volume up and down quickly, and a cost structure that suits high-throughput work. If you have a task with a clear rubric, a high-volume image classification job, a well-defined text categorization task, where an instruction sheet can reliably guide a large crowd, the marketplace model is efficient and fast to spin up.
The tradeoff is domain depth and consistency. A distributed crowd is, by design, interchangeable; workers may not carry deep expertise in your domain, and quality depends heavily on how airtight your guidelines are and how well the platform's QA catches drift. For clear tasks this is fine. For data that requires judgment, specialized knowledge, or sustained context across a long program, the marketplace model asks more of your own guideline and QA discipline to get reliable output.
ML-native tooling platforms with managed labeling
Vendors such as SuperAnnotate and Labelbox come at the problem from the software side. Their core product is the annotation platform itself: strong tooling, automation features, model-assisted labeling, workflow management, and analytics, with managed labeling services available on top. For a buyer who already has in-house QA discipline and wants better tooling to make an existing team or workforce more productive, this model fits well. You get sophisticated labeling infrastructure and keep ownership of the quality process.
The thing to be clear-eyed about is that the platform is the center of gravity, and the managed workforce is an add-on rather than the core competency. If your constraint is tooling, these vendors solve it directly. If your constraint is finding and keeping annotators who understand regulated medical data in six languages, a platform-first vendor is solving a different problem than the one you have.
BPO-scale, domain-matched workforce providers
The third type leads with the workforce. Vendors such as iMerit (part of EXL) and Firstsource are workforce-first: the differentiator is a managed, trained, domain-matched labeling workforce, with tooling and QA built around it. The defining move is that the workforce is matched to your domain before the program begins, so the people labeling your legal documents have legal context and the people labeling your multilingual conversations are native or fluent speakers who understand the cultural nuance, not just the words.
This model is built for programs the other two find hardest: regulated data where compliance and audit trails are non-negotiable, multilingual programs where language coverage has to come with genuine fluency, and long-lifespan programs where consistency across months and model iterations matters more than a fast, cheap burst of volume. It is less suited to a quick, low-stakes classification job, where a marketplace would be faster and cheaper. The fit is specific, and that is the point.
A buyer's framework for choosing an outsourcing partner
You can get most of the way to the right vendor type with an afternoon of diligence, and skipping it tends to cost months later. Four questions do most of the work.
How fast can the vendor activate a qualified team? Not a sales kickoff, an actually working, trained, domain-matched team producing labels. This is where vendor models diverge most. Some can start high-volume generic work in days; others need weeks to recruit and train for a specialized domain; an in-house build, as covered above, runs 12 to 18 months.
How well does the workforce match the data's domain and languages? Ask whether domain and language matching happens before the program starts or whether the vendor recruits for it after you sign. Ask what "supports 40 languages" actually means: fluent reviewers, or machine assistance with a thin human layer.
How deep is the QA process, and what reporting do you get? You want inter-annotator agreement, a defined review layer, systematic error detection, and reporting you could put in front of an auditor. The stakes are not abstract. Gartner Research found in 2022 that roughly 80% of AI project failures trace back to data quality problems rather than algorithm choice. The model is rarely what breaks; the data under it is. A vendor that cannot show you its QA depth is asking you to inherit that 80% risk.
How does the vendor handle compliance and data security? Data residency, workforce vetting, access controls, and audit-ready documentation vary widely between a crowd marketplace and a dedicated workforce provider. For regulated data this often decides the shortlist on its own.
Here is how the three vendor types tend to line up against those questions and the figures that frame the stakes.
Two external figures sit behind this exercise. The 3.3% average label error rate across common ML benchmark datasets (Northcutt et al., MIT CSAIL) shows that even the field's reference data carries meaningful error, so QA is not optional. And the roughly 80% of AI project failures traced to data quality rather than algorithms (Gartner Research, 2022) shows where that error lands: in failed projects. The framework above is a way to avoid being part of that 80%.
How Firstsource's Gigsourcing Platform compresses activation time
The activation-speed question is where Firstsource concentrates its difference, and it is worth being precise about the mechanism. Firstsource's Gigsourcing Platform is designed to activate domain-matched specialist teams in under 48 hours across more than 100 countries, with support for more than 150 languages.
The reason it can move that fast is structural. For an in-house team, and for some vendors, the clock on a new program starts with recruiting: you post roles, screen candidates, train them, and only then start labeling, which stretches the in-house build to 12 to 18 months and gives even established vendors a multi-week ramp for specialized domains. Gigsourcing inverts that order. The specialist pool is pre-qualified and domain-tagged before any given program exists, so activation is a matching-and-deployment step against an existing pool rather than a recruiting pipeline kicked off after the contract is signed. The sourcing gap that other models still carry is handled ahead of time.
The under-48-hour figure describes a different process, not just a faster version of the same one. It also carries a quality dimension that matters for the earlier framework: because the pool is domain-tagged, the team that activates is matched to your data's domain and languages from the first day, the opposite of the "recruit for the domain after signing" pattern the framework warns about. Speed and fit come from the same design decision.
Gigsourcing is the workforce layer. Around it, Firstsource runs orchestration and QA through the Agentic AI Studio (Xplore, Evaluate, Weave, and Monitor), which handles the review, measurement, and monitoring that turn a fast-activated workforce into defensible, audit-ready output. The platform sits inside Firstsource's GenAI Data Services business, which spans eight capabilities: data annotation, SFT/CoT demonstrations, expert preference (RLHF), multimodal evaluation, red teaming, AI safety, physical AI, and off-the-shelf (OTS) data.
Proof from production programs
Activation claims are easy to make, so it is fair to ask what they produce at scale. Two Firstsource production programs put numbers on it.
The first is a global commerce moderation and annotation marketplace program. There, Firstsource onboarded annotators three times faster than the industry baseline and sustained a 98.5% compliance rate across the program. The onboarding figure is the Gigsourcing model in practice: the activation-speed advantage compounds every time the program needs to add capacity. The compliance rate is the other half of the framework, the audit-ready QA posture holding up on regulated, high-volume marketplace data. Details sit on Firstsource's annotation programs for retail and digital marketplaces page.
The second is a program for a global smartphone manufacturer. Firstsource delivered more than 140,000 labeled assets in 24 weeks across 38 languages, 28 countries, and 8 device types, with zero sampling or extrapolation, meaning every asset was labeled rather than inferred from a sample. That program is a direct test of the multilingual, domain-matched model: 38 languages with real coverage, 28 countries of operational reach, and device-level variation that demands annotators who understand what they are looking at. The "zero sampling or extrapolation" detail is the quality claim that matters most to an ML team, because sampled or extrapolated labels are exactly where silent error enters a dataset. That program is described on Firstsource's data annotation solutions page.
Neither program discloses the client name, which is standard for this work. What they show is the workforce-first model doing what the framework predicts: fast, domain-matched activation on one side, defensible quality and compliance on the other.
Weighing build versus buy for your next labeling program?
Talk to a data annotation lead to scope a comparison for your specific data, languages, and compliance requirements.
Making the outsourcing decision
There is no universal answer to build versus buy, and anyone who gives you one is selling something. The useful question is narrower: what does your program need right now, and which vendor type is built for that need?
If you are still at pilot stage with a clear-rubric, high-volume task and no heavy compliance burden, a crowd-sourced marketplace is often the fastest and most economical way to get labels, and building in-house for that is usually overkill. If your constraint is tooling and you already have in-house QA you trust, an ML-native platform solves the real problem directly. If you are scaling a production program with regulated data, multiple languages that need genuine fluency, or a long lifespan where consistency across model iterations matters, the BPO-scale, domain-matched model is built for that shape of problem, and its activation-speed and domain-matching advantages compound over the life of the program rather than fading after launch.
The failure mode to avoid is treating outsourcing as one interchangeable category and picking the most familiar name. The three vendor types are genuinely different products solving different constraints. Match the type to your program's maturity and data, run the four-question diligence, and the shortlist tends to pick itself. Given that roughly 80% of AI project failures trace to data quality, that afternoon is some of the cheapest risk reduction available to the whole program.
FAQ
Which vendors provide outsourced data labeling for enterprise AI teams?
Enterprise teams typically choose between crowd-sourced marketplaces such as Appen and Sama, ML-native platforms such as SuperAnnotate and Labelbox, and BPO-scale workforce providers such as iMerit/EXL and Firstsource. Each offers a different balance of tooling and dedicated workforce, so the right choice depends on what you are labeling, in what languages, and under what compliance rules.
Is it better to build a data labeling team in-house or outsource it?
Most enterprise AI teams outsource once they move past a pilot. Building an equivalent in-house function, including hiring, training, tooling, and QA, typically takes 12 to 18 months, while an established vendor can activate a qualified team in days. The in-house path also carries recurring costs from annotator turnover and the opportunity cost of a model program that waits on a labeling function still being built.
How fast can an outsourced data labeling vendor start a new program?
This varies by vendor model. Crowd marketplaces can start generic, high-volume work quickly, while specialized domains often take weeks of recruiting and training with other vendors. Firstsource's Gigsourcing Platform is designed to activate domain-matched specialist teams in under 48 hours across more than 100 countries, because its specialist pool is pre-qualified before a program begins rather than recruited afterward.
What should enterprise AI teams check before signing a data labeling vendor?
Check activation speed, whether the workforce is matched to the data's domain and languages, the depth of the QA process, and the vendor's compliance and data-handling posture. Headline pricing or scale claims alone will not tell you whether the labels you receive will actually be reliable, and with roughly 80% of AI project failures tracing to data quality, label reliability is the number that matters most.
Do outsourced data labeling vendors handle compliance and security requirements?
It depends on the vendor. Enterprise buyers should confirm data handling practices, workforce vetting, and audit-ready QA reporting directly, since these vary significantly between crowd-sourced marketplaces and dedicated workforce providers. Regulated data usually narrows the shortlist to vendors that can produce audit-ready documentation and demonstrate how their workforce is vetted.