What is an agent copilot in a contact center?
TL;DR
- Agent copilots use AI to assist contact center agents during live customer interactions by retrieving relevant information, suggesting responses, detecting sentiment cues, and automating after-call documentation.
- Unlike chatbots that interact directly with customers, agent copilots support human agents while keeping them in control of conversations, decisions, and complex or sensitive issues.
- Agent copilots can improve key metrics such as average handle time (AHT), first-call resolution (FCR), and customer satisfaction (CSAT) by reducing search time, automating administrative tasks, and enabling faster, more effective support.
Forty-five percent of contact center calls require agents to search for information mid-conversation, according to Verint's State of Agent Experience 2026 survey of 1,000 agents. Nearly half the time, your customer is waiting while your agent hunts through tabs, knowledge bases, and policy documents for the right answer.
An agent copilot takes that search off the agent's plate so they can focus on the person on the other end of the line. The term now covers everything from a lightweight suggestion widget in a CRM to a fully operated AI capability running inside a live contact center program.
Those aren't the same thing, and buying the wrong one costs real money. This piece walks through what an agent copilot is, what it does during a call, how it differs from a chatbot, and where the line falls between a copilot you configure yourself and one that comes as a managed capability.
What is an agent copilot?
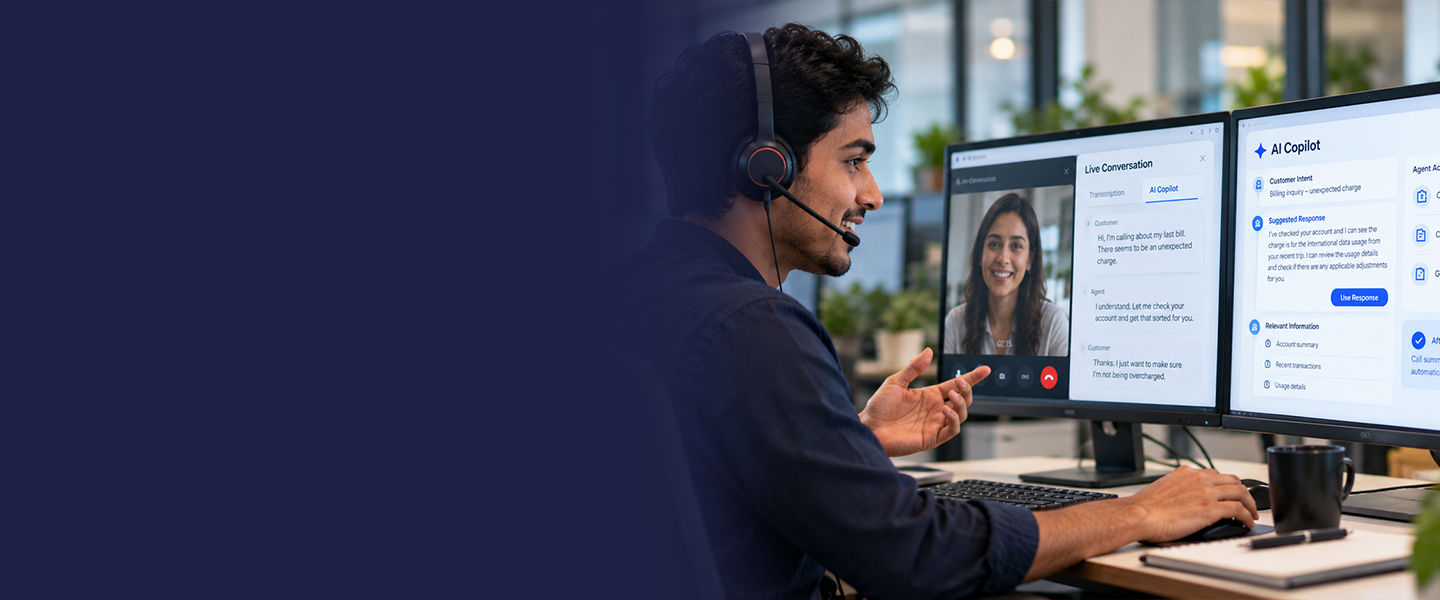
An agent copilot is AI that assists a human agent during a live customer interaction. It listens to the call or reads the chat in real time, pulls relevant information from connected systems, suggests responses, and handles the documentation that stacks up after the customer hangs up.
The agent stays in charge of the conversation. The copilot stays behind them, feeding them what they need.
The key word in that definition is assists. A copilot doesn't take the call or decide the outcome. It doesn't speak to the customer. A human agent still owns the judgment calls: whether to make a goodwill exception, when to escalate, how to handle a customer who's upset for reasons no knowledge base article covers.
The copilot's job is to strip away the friction around those judgment calls so the agent has more attention to spend on them.
Why the human stays in the loop
Regulated interactions make the clearest case. A financial services agent authorizing a refund, a healthcare agent discussing a claim, an insurance agent binding coverage: these conversations sit inside compliance frameworks that demand accountable human decisions. The copilot can surface the policy, draft the disclosure, and log the outcome. The agent still has to say the words and own the call.
There's also the emotional dimension. A customer whose flight was cancelled the night before their mother's funeral doesn't want a machine reading a script. They want a person who can hear them and adapt. Copilots excel at retrieval and drafting. They aren't built to meet a stranger where they are in a hard moment. Keeping the agent in the loop isn't a technical limitation you'll engineer around. It's the design.
What an agent copilot does during a call
The core functions are consistent across most serious copilot products. Where they differ is in accuracy, integration depth, and how much tuning it takes to get them working on your data. Four functions anchor the value: information retrieval, response drafting, real-time sentiment signaling, and after-call automation.
Information retrieval
When the customer asks a question, the copilot searches connected knowledge sources and surfaces what looks most relevant. That might be a policy document, product spec, troubleshooting article, or previous ticket for the same customer. Good retrieval is grounded: the copilot cites where the answer came from so the agent can verify before repeating it.
Response drafting
For chat and email, the copilot writes a suggested reply the agent can send, edit, or discard. For voice, it drafts talking points or suggested phrasing the agent can adapt. The draft is a starting point, not a script. Agents who trust the drafts skim and send. Agents who don't, retype. The point is that nobody stares at a blank composer window while a customer waits.
Real-time sentiment cues
The copilot listens for signals that the customer is frustrated, confused, or ready to churn, and flags the agent. Sometimes the cue is a color change on the desktop. Sometimes it's a prompt: the customer has repeated the same question twice; try acknowledging before answering. Sentiment cues work best as a nudge, not a verdict. The agent still reads the room; the copilot makes sure nothing important sails past unnoticed.
After-call automation
When the call ends, the copilot writes the summary, tags the disposition, updates the CRM, and drafts any follow-up email or task. The agent reviews and confirms. Verint's State of Agent Experience 2026 found that 54% of calls require after-call work. That's the tail on every conversation, and it's where copilots pay for themselves most visibly.
A realistic call from start to finish
Picture an inbound call to a broadband provider. The customer's internet has been dropping for three days. Before the agent has said hello, the copilot recognizes the caller from the ANI, pulls the account, and posts a compact panel on the agent's desktop: two open tickets, a recent outage in her postal code, three prior calls in the last six weeks tagged with intermittent connectivity, and a contract renewal window opening next month. The agent has that context in the first two seconds instead of building it from scratch.
The agent leads with acknowledgment: yes, we saw the outage, and we can see your line has been unstable since. As she talks, the copilot pulls the diagnostic history from the network side and highlights that a line card in her exchange was flagged yesterday. It surfaces the escalation path the agent should use, along with the standard credit calculation the account's service-level agreement (SLA) allows.
The agent didn't have to open the SLA document, calculate the prorated amount, or remember the escalation code. All three appeared where he'd look next. He confirms the credit amount and offers it.
Halfway through, the customer starts to sound resigned. The copilot's sentiment cue turns amber and prompts the agent to slow down and check whether anything else is on her mind. She mentions she's been thinking about switching providers. The agent moves to a retention path the copilot has already surfaced, with the two offers she qualifies for and the one she doesn't. He picks the one that fits her stated concern, not the default, and the copilot logs the reasoning.
The call ends. The copilot writes the summary in the format quality assurance (QA) expects, applies the credit code, opens the retention offer ticket in the right queue, drafts the confirmation email in the customer's preferred language, and flags the line card issue for the network operations team so the next caller from that exchange gets a faster answer. The agent scans, edits one line of the summary, and sends. The whole after-call block takes about 90 seconds instead of five minutes, and the record is complete enough that the next agent who picks up this customer won't start from zero.
Every function did its job. None of them replaced the agent's judgment about when to slow down, which offer to pick, or how to close a call that started as a complaint and ended as a save.
Agent copilot vs chatbot
These two products get confused often, and the confusion has cost organizations money.
A chatbot talks to the customer. It sits on the website, in the app, or on the messaging channel and handles the interaction directly. The customer types, the bot answers. No human in the middle. When the bot can't cope, it hands off to an agent.
An agent copilot talks to the agent. The customer never sees it and, in most deployments, doesn't know it's there. It works behind the human, feeding them information and handling documentation. The conversation the customer is having is with a person.
Where does each fit? Chatbots earn their keep on high-volume, low-variability tasks: order status, password resets, appointment booking, simple returns. Copilots earn theirs on the interactions that reach a human: the ambiguous, the emotional, the regulated, the ones where the answer isn't in a single field. In a mature contact center, both exist. The chatbot handles what it can, and the copilot makes the agent faster and more accurate on everything that lands with a person.
Copilot as a Feature vs Copilot as a Managed Capability
Agent copilots reach contact centers in two ways: as a feature built into a contact center platform, or as a capability delivered within a managed operation.
Copilot as a feature. Several contact center platform vendors offer agent copilots built into their platforms. Their public documentation describes real-time guidance for agents, including suggested next actions, and describes administrators configuring the copilot’s knowledge sources and settings through the vendor’s own tools.
Copilot as a managed capability. Firstsource offers Agent Copilot & Real-Time Intelligence within its CX operations. The company describes it as real-time desktop overlays, live sentiment signals, and next-best-action guidance delivered directly into live customer operations, with the aim of cutting handle times. It sits within Kairos, the operating system behind Intelligence That Operates, whose Operations Intelligence sensors mine 100% of live customer interactions.
The company says it is accountable for the operation, the advisors, the AI, and the outcomes, under one contract and one team, and that it is measured on CSAT, handle time, and complaint volumes. It also says it integrates and operates partner technology under Kairos.
Where the models differ. In the feature model, the customer’s administrators configure and manage the copilot inside the vendor’s console. In the managed model, the provider operates the copilot within the program and is measured on CSAT, handle time, and complaint volumes.
What outcomes an agent copilot is measured against
Three metrics anchor most agent copilot business cases: AHT, first-call resolution (FCR), and CSAT. Each connects to the copilot's core functions through a specific mechanism.
Average handle time
AHT is total talk time plus hold time plus after-call work. Copilots move it through two channels.
In-call, faster retrieval and drafted responses cut the silence while an agent searches. Verint's State of Agent Experience 2026 found that 45% of calls require in-call information search.
Consider a 500-seat operation handling 80,000 calls a month. If 36,000 of those calls include a search moment, and the copilot cuts 10 seconds from each one, that's 100 hours of hold time removed every month.
After the call, automated summaries and CRM updates compress the wrap block. Per the same Verint study, 54% of calls require after-call work. When the copilot writes the summary and the agent reviews and confirms, a five-minute wrap can drop to 90 seconds. Across thousands of calls a day, that compression frees capacity you can reinvest in coaching or absorbing volume spikes.
Industry sources report typical AHT reductions of 20 to 30% after agent copilot deployment, though the actual figure depends on where the baseline was, how disciplined the tuning cycle is, and whether agents trust the copilot enough to lean on it.
First-call resolution
FCR moves when the agent gets the right answer the first time. Copilots help by surfacing the correct policy or troubleshooting step at the moment of decision and by exposing prior interaction history so the agent doesn't repeat a failed fix.
The mechanism is precision of retrieval. A copilot that retrieves the wrong article confidently will hurt FCR, not help it, which is why grounding and citation matter and why ongoing tuning is not optional.
When an agent sees a cited source alongside a suggestion, they can verify in seconds. When they see an unsourced draft, they second-guess it, and the call gets longer instead of shorter.
FCR is also sensitive to knowledge base quality. A copilot inherits the strengths and the gaps of whatever it's reading, and part of running the capability well is closing those gaps as they surface in the transcripts.
Customer satisfaction
CSAT is what the customer felt about the interaction. Copilots influence it by shortening waits, reducing repeated questions, and freeing the agent's attention for the human side of the conversation.
A well-run copilot doesn't make agents sound like robots. It makes them sound like agents who have every answer at hand and aren't putting you on hold to go find one. AHT and FCR are the operational reads, and CSAT is what the customer noticed when both moved the right way.
Where this leaves you
Agent copilots reach contact centers in two ways: as a feature built into a contact center platform, which the client’s administrators configure in the vendor’s tools, or as a managed capability that the provider runs within the operation. Firstsource’s Agent Copilot & Real-Time Intelligence is the managed option. It delivers real-time desktop overlays, live sentiment signals, and next-best-action guidance into live customer operations, and the company says it is measured on CSAT, handle time, and complaint volumes.
To talk through how a managed copilot would fit your program, and where accountability would sit, talk to a Firstsource CX lead.
FAQ
What is an agent copilot in a contact center?
An agent copilot is AI that assists a human agent during a live customer interaction. It surfaces relevant information from connected systems, drafts suggested responses, signals real-time sentiment cues, and automates after-call documentation. The agent stays in charge of the conversation and the judgment calls.
What's the difference between an agent copilot and a chatbot?
A chatbot talks to the customer directly, usually on a website, app, or messaging channel, and handles the interaction without a human. An agent copilot talks to the agent, not the customer, working behind the scenes to feed information and draft responses during a live human conversation.
Is agent copilot technology the same across every contact center platform?
No. Products like NICE Enlighten Copilot, Genesys Agent Copilot, and Talkdesk Copilot are features you configure inside the platform you already own, with native integration and self-service tuning. A managed capability, such as Firstsource's Agent Copilot & Real-Time Intelligence, is deployed, tuned, and operated as part of a live program with accountability for outcomes.
What metrics does an agent copilot typically improve?
Common metrics are average handle time (AHT), first-call resolution (FCR), and customer satisfaction (CSAT). AHT drops because retrieval and drafted responses cut in-call search time and automated summaries shrink after-call work. FCR improves when the right answer surfaces at the moment of decision. CSAT rises when waits shorten and agents can spend more attention on the human side of the call.