What are the main types of data annotation used in computer vision vs. NLP?
TL;DR
- Computer vision annotation mainly involves labeling visual elements: bounding boxes, polygon and pixel-level segmentation, keypoint and landmark tagging, 3D cuboids and LiDAR point clouds, and object tracking across video frames.
- NLP annotation mainly involves labeling language elements: named entity recognition, text and intent classification, entity linking, sentiment tagging, and preference ranking used in RLHF.
- Some annotation work, such as video-language grounding, gesture recognition, and voice transcription, sits across both fields and is usually called multimodal annotation.
- The type of annotation a model needs depends entirely on what the model has to do, which is why matching annotation type to model task matters more than assuming one universal labeling process covers every use case.
"Data annotation" sounds like one job, but it covers a wide family of techniques that differ by the kind of data you are labeling and the kind of thing the model is supposed to learn. A self-driving perception model and a customer-support intent classifier both depend on annotated data, yet almost nothing about the actual labeling work overlaps. The perception model needs someone to draw boxes around cars and pedestrians, trace lane boundaries, and track those objects as they move through traffic. The intent classifier needs someone to read short messages and decide whether a customer is asking about billing, requesting a refund, or reporting a bug. Same umbrella term, completely different work.
That gap is the reason it helps to look at annotation by category. This article walks through the main types of computer vision annotation, the main types of NLP annotation, the multimodal work that sits across both, and the quality question that decides whether any of it helps a model. By the end you should be able to name the annotation type a given model task calls for, and know what to ask a vendor to prove they can do it. For a short definition to anchor the rest, the data annotation glossary entry is a useful reference.
What data annotation means across modalities
At its core, annotation is the act of adding structure to raw data so a model has something to learn from. Raw data on its own carries no labels. A photograph is a grid of pixel values. A product review is a string of characters. Neither tells a model what matters inside it. Annotation is where a human (or a human-supervised process) marks the parts that matter and names them, so a model can learn the mapping from input to the thing you care about.
What changes across modalities is the kind of structure you add. In computer vision, the structure is spatial. You are telling the model where things are in an image and what they are: this region is a car, these pixels belong to a tumor, this point is the corner of an eye. The labels live in coordinates, shapes, and pixel masks. In NLP, the structure is linguistic. You are telling the model which spans of text mean what: these three words are a company name, this sentence expresses frustration, this passage is a billing question. The labels live in offsets, categories, and relationships between words.
Multimodal annotation is where both kinds of structure apply at once. A video clip paired with a spoken instruction needs spatial labels for what is happening on screen and language labels for what the instruction means, tied together so the model learns the connection. That combination is harder to staff and harder to get right, which is part of why it sits in its own category later in this article. The common thread across all three is simple: the annotation schema has to match what the model is being asked to do, because the model can only learn from the structure you give it.
Main types of computer vision annotation
Computer vision annotation covers a range of techniques, and which one you need depends on what the model has to detect, locate, or track. A model that only needs to know whether a car is present somewhere in the frame needs far less precise labels than one that has to steer around that car in three dimensions. The types below run roughly from fastest and simplest to most technically demanding.
Bounding boxes and object detection
Bounding boxes are the most common and the fastest form of computer vision annotation. An annotator draws a rectangle around each object of interest and assigns it a category: car, person, traffic sign, product. The box tells the model roughly where the object sits and what it is, which is enough for detection and counting tasks.
This is the workhorse of a lot of applied vision. Retail shelf monitoring uses it to count facings and spot out-of-stock products. Security and surveillance analysis uses it to flag people or vehicles in a feed. Early-stage autonomous vehicle perception uses it before the heavier 3D work begins. Boxes are quick to draw and easy to check, which keeps the cost per label low, but they also approximate shape loosely. A rectangle around a cyclist includes a lot of background, so when the exact outline matters, boxes are not enough.
Polygon and pixel-level segmentation
When a task needs the real shape of an object rather than a rectangle around it, you move to segmentation. Polygon annotation traces the outline of an object point by point. Pixel-level (semantic or instance) segmentation goes further and labels every pixel as belonging to a class, producing a precise mask.
Segmentation matters wherever the boundary carries meaning. A medical model estimating tumor size needs the actual tumor boundary, not a box that bleeds into healthy tissue. An agricultural model separating crop from soil needs the exact edge between plant and ground to measure coverage. The trade-off is time. Tracing an outline or masking an object pixel by pixel takes considerably longer than dropping a box around it, sometimes by an order of magnitude, so segmentation work costs more and demands annotators who stay consistent about where one object ends and the next begins.
Keypoint and landmark annotation
Keypoint annotation marks specific named points on an object rather than its whole area. On a face, those points might be the corners of the eyes, the tip of the nose, and the edges of the mouth. On a body, they might be the shoulders, elbows, wrists, hips, and knees that make up a pose skeleton.
Models trained on keypoints power gesture recognition, fitness and motion tracking, and driver-monitoring systems that watch for drowsiness or distraction. The hard part here is consistency across scale. If one annotator places the "left wrist" point slightly differently than another, or drifts over the course of thousands of images, the model learns a blurry target. Keypoint work lives or dies on annotators applying the same definition of each point the same way, image after image, which is why it needs tight guidelines and heavy review.
3D cuboids and LiDAR point cloud annotation
The most technically demanding computer vision annotation sits in three dimensions. Here annotators place 3D boxes (cuboids) around objects and label points inside LiDAR point clouds, the sparse 3D scans that autonomous vehicles and robots use to sense the world. Instead of a flat rectangle on an image, the label captures an object's position, size, and orientation in space.
Autonomous driving and robotics both depend on this. A self-driving stack has to know not just that a car is ahead but how far away it is, which way it faces, and how big it is. That requires annotators who understand sensor geometry, how a camera image and a LiDAR sweep line up, and how to reason about objects they can only partly see. It is slow, specialized work, and the pool of people who can do it well is much smaller than the pool who can draw 2D boxes.
Video object tracking
Video tracking adds a time dimension to the techniques above. Instead of labeling a single frame, annotators label objects across a sequence of frames and preserve each object's identity as it moves, appears, and disappears. A pedestrian who walks behind a bus and comes out the other side has to keep the same ID throughout.
Tracking underpins surveillance analytics, sports analysis that follows players and the ball, and traffic studies that measure how vehicles flow through an intersection. The annotation can be built on boxes, segmentation masks, or keypoints, but the added challenge is continuity. The model learns from whether the labeling kept each object coherent over time, so a single identity swap in the middle of a clip can teach the wrong lesson.
Main types of NLP annotation
NLP annotation follows the same basic logic as computer vision annotation: you add structure that tells the model what matters, and the type you choose depends on the task. The difference is that the structure lives in words, phrases, and documents instead of pixels and coordinates. The categories below cover the work that shows up most often.
Named entity recognition and entity linking
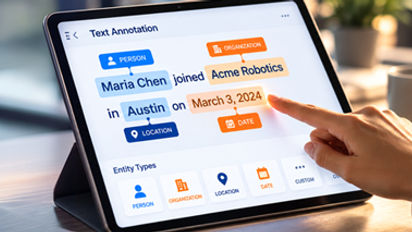
Named entity recognition (NER) labels spans of text by category: this span is a person, this one a company, this one a location, date, or product. It sounds simple until you get to boundaries. Does "New York Times" get tagged as one organization, or does "New York" come out as a location inside it? Annotators have to agree on exactly where an entity starts and ends, and strict boundary agreement is what separates usable NER data from noise. The NER reference in the data annotation glossary covers the basic definition.
Entity linking goes one step past NER. Once a span is labeled as, say, a company, entity linking connects it to a specific record in a knowledge base, so the model knows that this "Apple" is the technology company and not the fruit. NER plus linking is what powers information extraction, search, and the structured fields behind a lot of enterprise AI.
Text and intent classification
Classification assigns a single label to a whole passage rather than tagging spans inside it. A support ticket gets labeled "billing question." A product review gets labeled positive or negative. A news article gets a topic. Intent classification is the conversational cousin: given what a user just typed or said, which action are they asking for, such as "check order status" or "cancel subscription"?
Both forms depend on clear, non-overlapping category definitions. If "billing question" and "refund request" overlap in the guidelines, annotators will split hairs differently and the model will inherit the confusion. Good classification data starts with a label set where every example has one obvious home, and that design work happens before any labeling begins.
Sentiment and sentiment-adjacent tagging
Sentiment annotation labels the emotional tone of text: positive, negative, or neutral at the simplest level, and more granular signals like sarcasm, frustration, or urgency when the use case calls for it. It is one of the more subjective annotation types, because reasonable people read tone differently. A short review that says "well, that was fast" could be sincere or sarcastic depending on context an annotator may not have.
Because of that subjectivity, sentiment work leans harder on inter-annotator agreement checks than most other NLP types. Teams measure how often independent annotators land on the same label, surface the disagreements, and refine guidelines until the gray areas shrink. Skipping that step produces a dataset that looks fine but teaches the model an inconsistent notion of tone.
Preference ranking and RLHF-style comparison labels
Preference ranking is the annotation type behind reinforcement learning from human feedback (RLHF), the method used to align large language models. Instead of labeling one piece of text, annotators compare multiple model outputs for the same prompt and rank them by helpfulness, accuracy, or safety. The model learns which kinds of responses people prefer.
This is some of the hardest language annotation to staff well. Telling a clearly good answer from a clearly bad one is easy. The value sits in the hard cases: an answer that reads fluently but contains a subtle factual error, or one that is technically correct but unsafe or unhelpful. Ranking those well requires annotators with enough subject knowledge and judgment to catch a plausible-sounding wrong answer, which is a different skill from tagging entities or tone.
Where computer vision and NLP annotation overlap: multimodal annotation
Some of the most demanding annotation work refuses to sit on one side of the vision/language line. Multimodal annotation labels data that combines visual and language structure, and it requires annotators who can hold both in their heads at once.
Video-language grounding is a clear example. A clip is paired with a text description or instruction, and the annotator has to connect the words to what is happening on screen: which object the instruction refers to, which moment in the video a sentence describes. The label ties a language span to a spatial and temporal region, so both kinds of structure have to be correct and correctly linked.
Gesture recognition tied to voice or device control is another. A system that lets someone control a device with a hand gesture plus a spoken command needs keypoint-style labels for the hand pose and language labels for the command, annotated together so the model learns the pairing. Audio transcription paired with text labeling fits here too: a transcriber writes down what was said, and that transcript then gets NER, intent, or sentiment labels on top, which means the same data passes through audio, language, and classification work in sequence. In all of these, the common requirement is annotators who can work across formats without dropping accuracy in either, and that is a narrower talent pool than either vision-only or language-only work.
Why annotation type and quality both affect model accuracy
Picking the right annotation type is necessary, but it is not enough on its own. A correctly chosen schema applied inconsistently still produces a weak model. Three different lines of research point at the same conclusion from different angles.
First, the data most teams trust is noisier than they assume. An MIT CSAIL study by Curtis Northcutt, Anish Athalye, and Jonas Mueller found an average label error rate of roughly 3.3% across commonly used machine learning benchmark datasets. These are the curated, widely cited datasets the field builds on, and even they carry errors in about one label in thirty.
Second, those errors cost accuracy. Noisy-label research cited via SitePoint reports accuracy drops of around 25% when label noise enters training data. That is not a rounding error. It is the difference between a model that ships and one that gets sent back.
Third, the industry keeps blaming the wrong thing. Gartner Research reported in 2022 that roughly 80% of AI project failures trace back to data quality rather than algorithm choice. Teams reach for a better architecture when the real problem is the labels underneath it.
Read together, these say the same thing. Choosing the right schema matters, and so does applying it consistently across every example. A keypoint program with a precise definition of each landmark still fails if annotators drift. A sentiment set with a clean label scheme still fails if inter-annotator agreement is never checked. Type and quality are two settings on the same dial, and both have to be right.
Why this matters when choosing a data annotation vendor
Here is the practical takeaway for anyone buying annotation. Vendors are not equally strong across computer vision, NLP, and multimodal work, even when their marketing suggests they can do all of it. A team that has drawn millions of bounding boxes may have almost no track record in RLHF preference ranking. A team strong at sentiment and classification may have never touched LiDAR. "We do data labeling" tells you very little, because the skills behind keypoint annotation, 3D sensor work, and preference ranking barely overlap.
So the useful move is to ask for proof in the specific type you need, not general labeling experience. If you need keypoint annotation, ask to see keypoint samples and the guidelines behind them. If you need RLHF-style comparison data, ask how the vendor recruits and qualifies the annotators who rank subtly different answers, and ask to see real ranked examples. Type-specific samples separate a vendor who has actually done the work from one who is confident they could. The data annotation solutions page is a reasonable place to see what type-specific evidence looks like in practice.
FAQ
What are the main types of data annotation used in computer vision vs. NLP?
Computer vision annotation includes bounding boxes, segmentation, keypoint and landmark tagging, 3D cuboids, and video tracking, while NLP annotation includes named entity recognition, text classification, sentiment tagging, and preference ranking for model alignment. The two sides label different kinds of structure, spatial for vision and linguistic for language, but follow the same logic of matching the labeling technique to what the model has to learn.
What is multimodal data annotation?
Multimodal annotation combines visual and language labeling techniques for tasks like video-language grounding, gesture recognition tied to voice commands, and transcription paired with text labeling, and it requires annotators who can work across both formats. Because the label ties a spatial or temporal region to a language span, both kinds of structure have to be correct and correctly linked, which makes it harder to staff than vision-only or language-only work.
Is named entity recognition part of computer vision or NLP annotation?
Named entity recognition is an NLP annotation type. It identifies and labels entities like people, organizations, and locations within text, which supports downstream tasks like information extraction and search. The hard part is boundary agreement, since annotators have to decide exactly where each entity starts and ends before the labels are useful.
Why does the type of annotation affect model accuracy?
Each annotation type is built to teach a model a specific skill, so using the wrong type, or applying it inconsistently, introduces label noise that MIT CSAIL research and related noisy-label studies show can measurably reduce model accuracy. MIT CSAIL found a roughly 3.3% error rate even in widely used benchmark datasets, noisy-label research via SitePoint reports accuracy drops of about 25% from label noise, and Gartner tied roughly 80% of AI project failures to data quality rather than algorithm choice.
Should I use the same data annotation vendor for computer vision and NLP work?
You can, but confirm the vendor has real, demonstrated experience in both areas, since strong bounding-box or segmentation work does not automatically mean a vendor is equally strong at entity tagging or preference ranking. Ask for type-specific samples in the exact annotation type you need, such as keypoint annotation or RLHF preference ranking, rather than accepting general labeling experience as proof.